State of AI model pricing, October 2026
The same 1,000 support replies cost $0.35 on the cheapest AI model and $35 on the dearest. Gemini 4 Argon doubles in price on 1 December. What moved in October, what three common jobs cost, and the prices our sources got wrong.
The same 1,000 customer-support replies cost $0.35 on the cheapest text model we track and $35 on the dearest: a 100× gap for the same job. The median model charges $4.56. Six of the ten cheapest models have open weights.
The biggest move is still to come: Gemini 4 Argon doubles on 1 December, from $2 to $4 per million input tokens and from $10 to $20 per million output tokens, according to Google’s pricing page. Anyone running Argon at volume has five weeks to test an alternative.
This is our first monthly report. It covers the 38 text models with a per-token list price, out of the 50 models we track. Every number links back to the open dataset, which anyone can download and check.
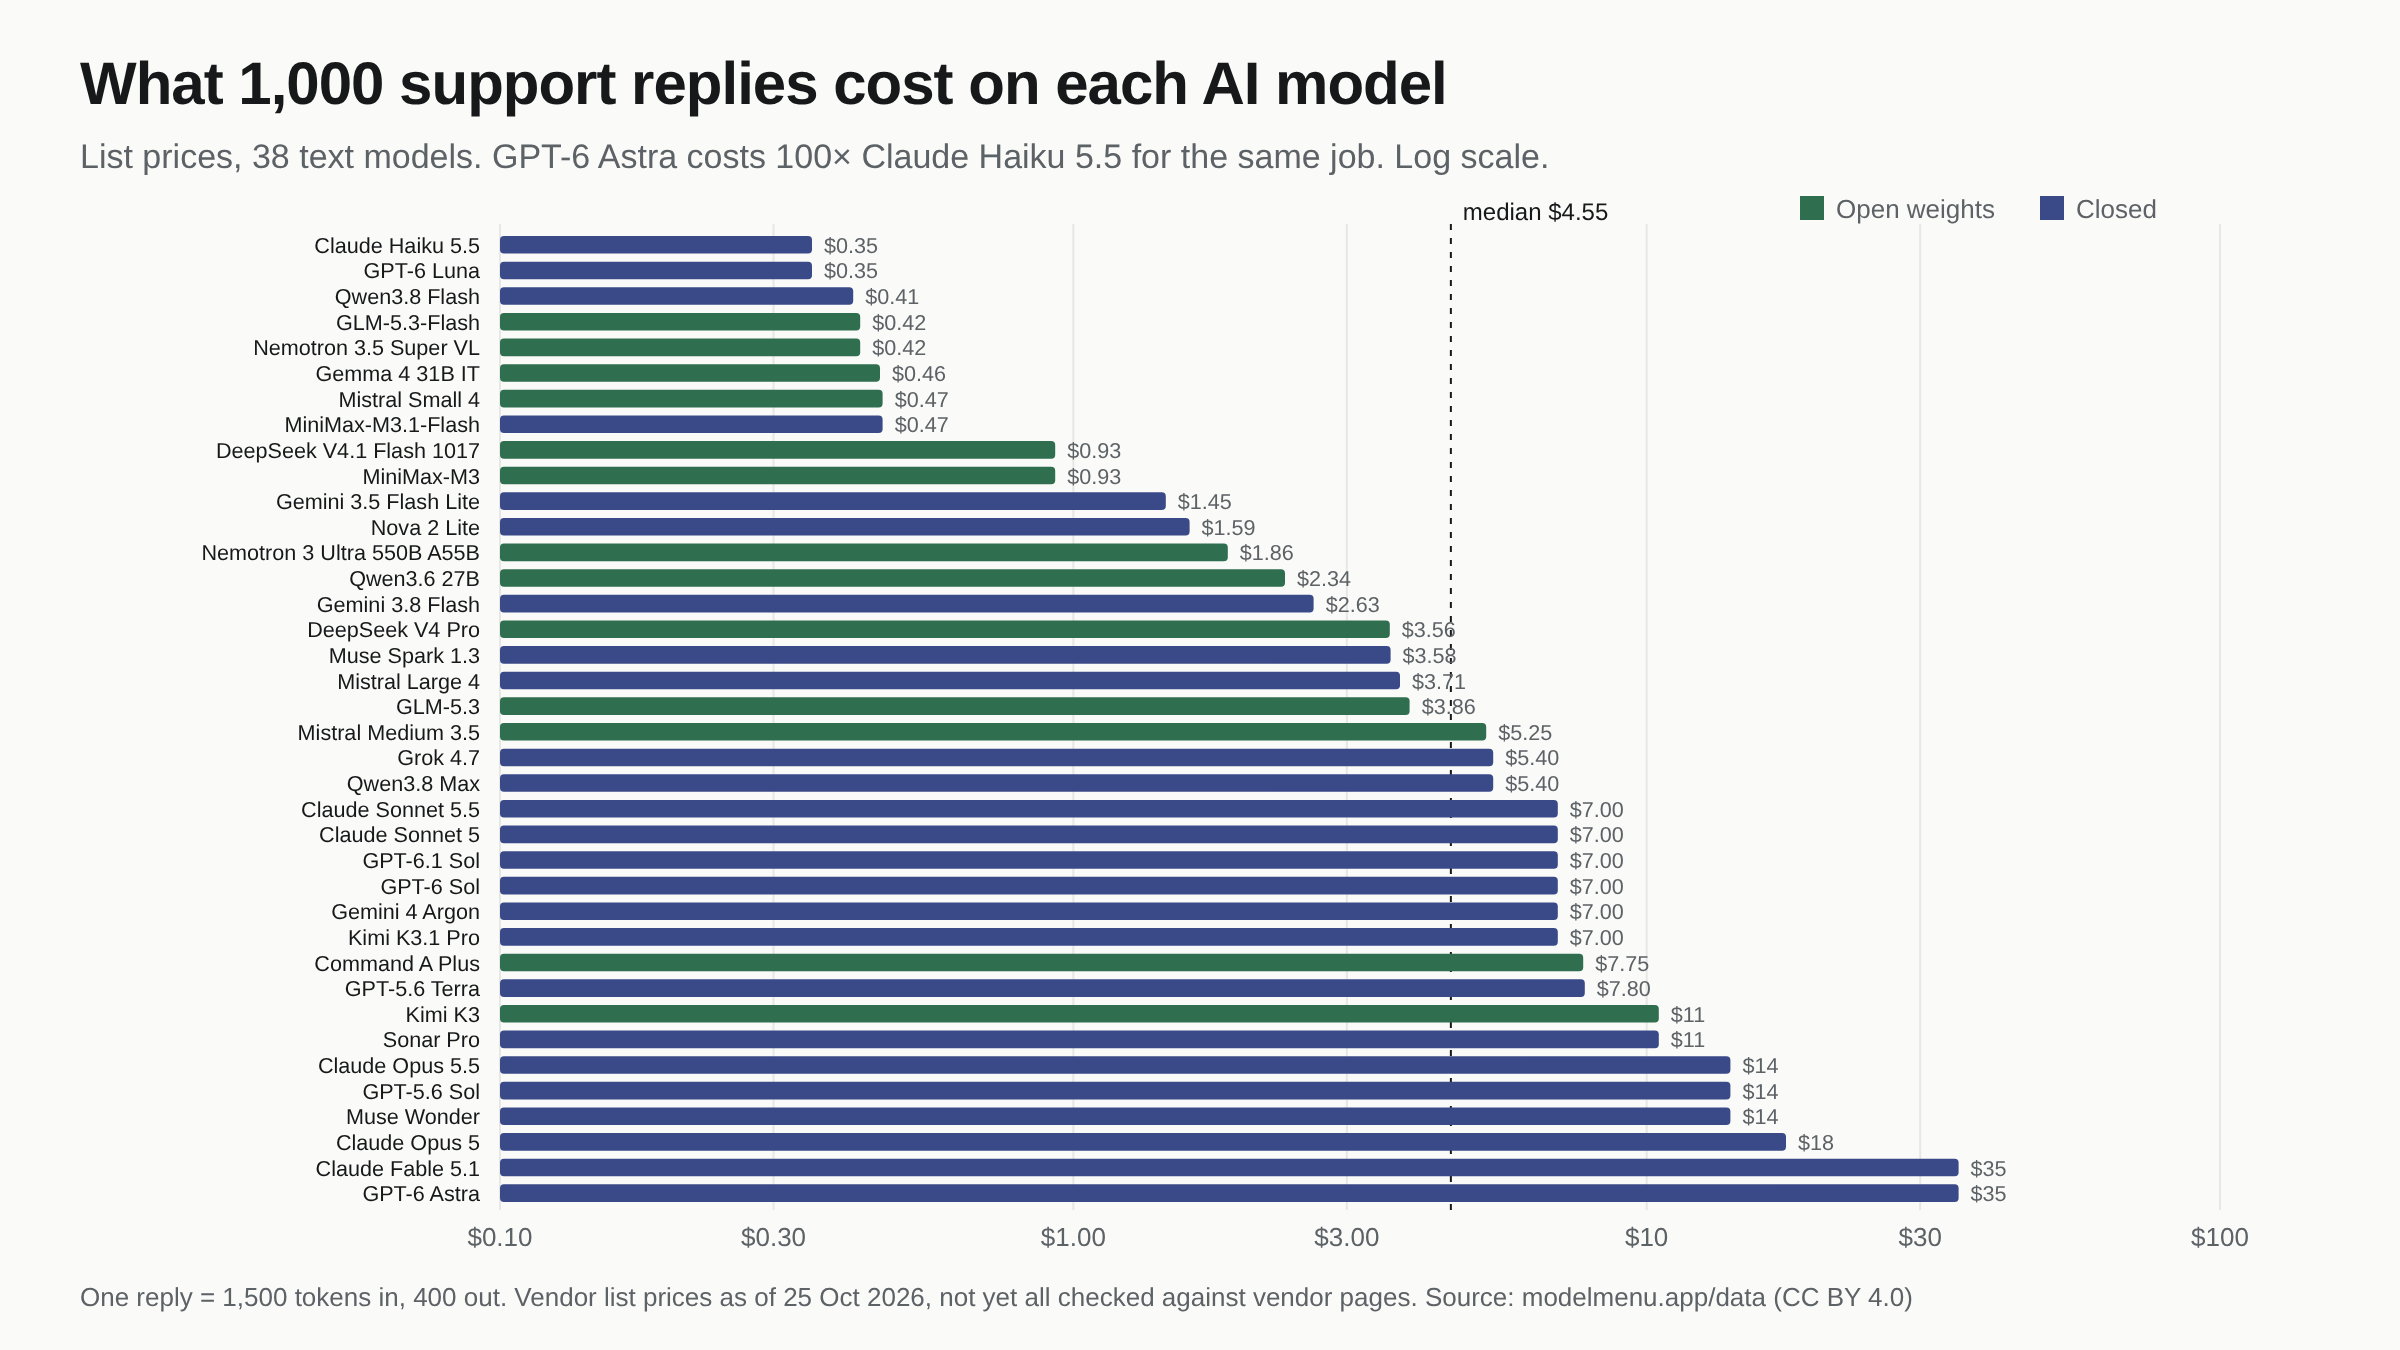
The numbers
| Measure | Value |
|---|---|
| Text models priced | 38 |
| Cheapest for 1,000 support replies | $0.35 (Claude Haiku 5.5, GPT-6 Luna) |
| Dearest for 1,000 support replies | $35.00 (GPT-6 Astra, Claude Fable 5.1) |
| Median | $4.56 |
| Open-weights models among the 10 cheapest | 6 |
| New text models released 25 Sep to 24 Oct | 10 |
| List-price changes on existing models in the month | 2 (one cut, one launch discount ending) |
| Announced change still to come | 1 (Gemini 4 Argon, 1 Dec, +100%) |
| Prices checked by hand against vendor pages for this report | 12 |
A support reply here is 1,500 tokens in (the customer’s message, some history and your instructions) and 400 tokens out, the same reference job the leaderboard uses.
What three common jobs cost
Cost of 1,000 jobs at list price. These are prices only: whether the cheap models do the job well is what our test rig measures, and its first results come in November.
| Job | Tokens in / out | Cheapest | Cheapest open weights | Dearest |
|---|---|---|---|---|
| Support reply | 1,500 / 400 | $0.35, Claude Haiku 5.5 or GPT-6 Luna | $0.43, GLM-5.3-Flash or Nemotron 3.5 Super VL | $35, GPT-6 Astra |
| Product description | 800 / 350 | $0.26, Claude Haiku 5.5 or GPT-6 Luna | $0.30, GLM-5.3-Flash or Nemotron 3.5 Super VL | $25.50, GPT-6 Astra |
| Contract summary (4 pages) | 6,000 / 600 | $0.90, Claude Haiku 5.5 or GPT-6 Luna | $1.20, GLM-5.3-Flash or Nemotron 3.5 Super VL | $90, GPT-6 Astra |
The six models in our first test batch, for the same three jobs:
| Model | Support reply | Product description | Contract summary |
|---|---|---|---|
| DeepSeek V4 Pro (open, peak rate) | $3.56 | $2.44 | $10.30 |
| Grok 4.7 | $5.40 | $3.70 | $15.60 |
| GPT-6.1 Sol | $7.00 | $5.10 | $18.00 |
| Gemini 4 Argon (to 30 Nov) | $7.00 | $5.10 | $18.00 |
| Kimi K3 (open) | $10.50 | $7.65 | $27.00 |
| Claude Opus 5.5 | $14.00 | $10.20 | $36.00 |
From 1 December, Gemini 4 Argon’s three figures become $14.00, $10.20 and $36.00, level with Claude Opus 5.5. DeepSeek charges half the peak rate outside its peak hours, so V4 Pro’s figures halve for most of the week (below).
What moved in October
- Claude Sonnet 5.5: cached input halved, from $0.20 to $0.10 per million tokens, on 7 October (Anthropic release notes). Input and output stay at $2 and $10. LiteLLM’s public price map picked it up 11 days later.
- Mistral Large 4’s launch discount ended. It launched on 6 October at 50% off for two weeks; from about 20 October it lists at $1.36 in and $4.18 out (Mistral). Some price trackers still show the discounted $0.68 and $2.09.
- Ten new text models. Claude Sonnet 5.5 (28 Sep), GPT-6.1 Sol (29 Sep), Mistral Large 4 (6 Oct), Claude Haiku 5.5 (7 Oct), Muse Wonder (12 Oct), Gemini 4 Argon (13 Oct), Nemotron 3.5 Super VL (15 Oct, open weights), DeepSeek V4.1 Flash (17 Oct, open weights), MiniMax-M3.1-Flash (19 Oct) and Kimi K3.1 Pro (23 Oct).
- New flagships held the line on price. Claude Opus 5.5 lists at $4 in and $20 out, below Claude Opus 5’s $5 and $25. GPT-6.1 Sol and Gemini 4 Argon both list at $2 and $10, and Argon only until 30 November.
Earlier moves, for context, from LiteLLM’s price map: GPT-5.6 Terra fell from $2.50/$15 to $2/$12 in early August, and GPT-5.6 Sol from $5/$30 to $4/$20 in late August or early September. DeepSeek went the other way: V4 Pro’s new pricing took effect on 16 August (DeepSeek), and LiteLLM’s figure for it rose from $0.435/$0.87 to $1.32/$3.96.
The prices our sources got wrong
We read prices from two open sources, models.dev and LiteLLM. On 24 October they disagreed on four text models, each time by exactly a factor of two. We checked every one against the vendor’s own page on 25 October.
| Model | models.dev | LiteLLM | Vendor page | Why they differ |
|---|---|---|---|---|
| DeepSeek V4 Pro | $0.66 / $1.98 | $1.32 / $3.96 | $1.32 / $3.96 peak, $0.66 / $1.98 off-peak | Time-of-day pricing |
| DeepSeek V4.1 Flash | $0.15 / $0.60 | $0.30 / $1.20 | $0.30 / $1.20 peak, $0.15 / $0.60 off-peak | Time-of-day pricing |
| Mistral Large 4 | $1.36 / $4.18 | $0.68 / $2.09 | $1.36 / $4.18 | Launch discount that ended about 20 Oct |
| Muse Spark 1.3 | $1.25 / $4.25 | $0.10 / $0.20 | $1.25 / $4.25 | A cheaper “contributor” tier whose prompts Meta may use |
Prices are input / output per million tokens. DeepSeek’s off-peak rate is half its peak rate and applies outside 01:00–04:00 and 06:00–10:00 UTC on weekdays: about 79% of the week, including weekends (DeepSeek pricing). We list the peak rate, because it is the most you can pay; at off-peak rates, DeepSeek V4 Pro’s 1,000 support replies cost $1.78 instead of $3.56. Our own record had stored DeepSeek’s off-peak rate; we have corrected it and noted the correction.
Also worth knowing before you compare: Claude Haiku 5.5 costs five times as much on prompts over 100,000 tokens, Grok 4.7 doubles over 200,000 tokens, and GPT-6.1 Sol charges twice as much for input and 1.5 times as much for output over 272,000 tokens. The tables above use the base tier.
How we made this
- Prices: list prices per million tokens on each model’s own API, as recorded on 24 October 2026 from models.dev (MIT licence), with the 12 prices named in this report checked by hand against vendor pages on 25 October. These are the same figures our site and dataset show. Other hosts and routers such as OpenRouter can be cheaper, especially for open-weights models (1,000 support replies on Kimi K3 cost about $4.68 through OpenRouter on 25 October), and each model page lists every endpoint. History before 24 October comes from LiteLLM’s public price map (MIT), read at weekly releases, so a change date is known to within one or two weeks. From 24 October on, our own pull runs every 6 hours.
- Jobs: tokens in and out per job are our assumptions, stated in each table. Real jobs vary.
- Not in this report: quality. A cheap model that fails the job is not a bargain. Our test rig runs ten small-business tasks on six models in early November; the next report names the cheapest model that passes for each job.
- Corrections: tell us through the disclosure page and we will fix and note it here.
The data behind every table is free to reuse under CC BY 4.0: download it. Get the next report and price-drop alerts by email from the alerts page, or follow the changelog.